Appendix H. Answers to the Self-Check Questions
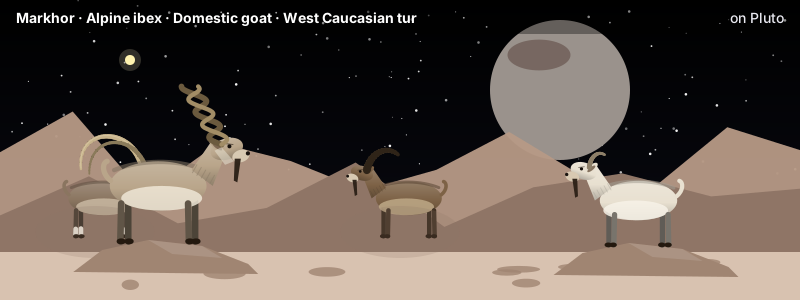
About the animals in this picture and where they are standing
- Markhor (Capra falconeri) lives in the mountains of Pakistan, Afghanistan and neighbouring regions. The males' horns twist in a corkscrew; the name is often explained as Persian for 'snake-eater'. It is Pakistan's national animal, and community-based conservation has helped some populations recover.
- Alpine ibex (Capra ibex) lives in the European Alps, usually above the tree line on steep rock, and is a famously sure-footed climber. Males carry horns that can reach about a metre. Hunting left only a small remnant, around the Gran Paradiso in Italy, by the early 1800s; reintroductions have since restored it across the Alps.
- Domestic goat (Capra hircus) descends from the bezoar ibex and is among the oldest domesticated animals. There are on the order of a billion of them, kept for milk, meat, fibre and as pack animals.
- West Caucasian tur (Capra caucasica) lives only in the western Caucasus, on steep slopes above the forest line. Its horns are short and heavy, curving outward and back, and it moves up and down cliffs with ease.
The scene is imaginary: it is set on Pluto, a dwarf planet with a heart-shaped plain of nitrogen ice; its largest moon, Charon, is about half its width. The animals are stylised drawings, shown where they could not live, for effect.
Worked answers, chapter by chapter.
Chapter 1: The Flow
1. Why does the testbench compare with !== and not !=, and what would a plain != let through?
Worked answer: != returns unknown (x) when either side contains an x or z bit, and an if on an unknown condition is treated as false, so the mismatch branch is silently skipped. A wire that nothing drives (for instance the output of a stage that was never built) is x, so with != a broken circuit whose outputs are x would be reported as correct. !== compares the four-state values literally, so x never equals a known bit and the mismatch is counted.
2. The golden model enumerates all 512 inputs. Roughly how many inputs does a circuit with two 32-bit operands have, and what does that do to the idea of "exhaustive"?
Worked answer: 2^64 (about 1.8 x 10^19) operand pairs, times 2 for a carry-in. At a billion tests per second that is about 600 years, so exhaustive testing is impossible. Testing then relies on directed corner cases, random inputs, structural arguments (a 32-bit adder is built from the same stage repeated, so testing small widths exhaustively says a lot) and, in this book, mutation counts that show how much a pass is worth.
3. Yosys reports 20 gates for the adder and 9 lookup tables for the same design. Why is neither number "wrong", and which would you quote for a chip?
Worked answer: they count different things. A standard-cell chip is built from fixed small gates, so a gate count (and, with a library, an area) is the relevant figure; an FPGA is built from programmable lookup tables, so a LUT count is. The same logic packs differently into each. For a chip you would quote the gates or cell area after mapping to the process's real cell library, which this book does not have, so it quotes the generic-gate count and labels it as such.
4. A testbench that tried only cin = 0 would miss exactly one of the ten mutants. Which one, and why does that make exhaustiveness valuable?
Worked answer: the mutant that ties the carry-in to zero (assign c[0] = 1'b0;). With cin always 0 the tied-off circuit behaves identically, so a test that never sets cin to 1 cannot tell them apart; the other nine mutants change behaviour even with cin = 0. This is the typical way a weak test fails: not by missing the big mistakes but by never exercising the input that distinguishes one particular mistake. Exhaustive testing leaves no such input unexercised.
5. A mutant survives. What is the first question to ask, and what are the two possible answers?
Worked answer: "Is this mutant equivalent to the original?", that is, does it behave identically for every possible input? If it does (like writing a | b for a ^ b in the carry's propagate term), the survivor is harmless and no test could ever catch it; it should be reported and set aside. If it does not, there is an input on which the circuit differs and the test never tried it: a gap in the test, which the fix is to close by adding that input.
Chapter 2
1. Why is -128 x -128 the worst case for the accumulator, and how many such products does it take to overflow 32 bits signed?
Worked answer: the product is +16384 = 2^14, larger in magnitude than any other int8 product (127 x 127 = 16129; -128 x 127 = -16256). The signed 32-bit maximum is 2^31 - 1, so 2^31 / 2^14 = 131,072 products overflow it: the 131,072th takes the sum to exactly 2^31, which is one past the maximum. The test uses 4 x 32,768 = 131,072 cycles.
2. In mul8_sa, why must the row for bit 7 of b be subtracted?
Worked answer: in two's complement the top bit has weight -128, not +128. The product a * b therefore contains a * (-128) when that bit is set, so its shifted row of a has to be subtracted. Adding it instead gives a result that is wrong by 2 x 128 x a for every negative b, which the mutant "the sign row is added instead of subtracted" and the exhaustive test show.
3. Why does the MAC compute its sum in 33 bits instead of 32?
Worked answer: the sum of a 32-bit value and a 16-bit value can need 33 bits. Computing in 32 would already have discarded the carry, so the overflow could not be detected (and the saturating version could not know which limit was crossed). The mutant "the sum is only 32 bits wide" is caught by the overflow runs.
4. The two multiplier styles cost 401 and 398 gates. What can you conclude, and what can you not?
Worked answer: that for this flow (Yosys 0.33, default synthesis, generic gate library) hand-built shift-and-add buys nothing over writing *: the tool already finds a comparable structure. Not concluded: anything about speed (no timing was measured), anything about other tools, or that structure never matters (a hard multiplier block in a real process, or a different architecture such as a Booth multiplier, can change the cost).
5. A testbench ends its loop when the expected value is x. Why does it work in Icarus and hang in Verilator?
Worked answer: Icarus is four-state, so reading past the end of the vector memory yields x and the loop test sees it. Verilator is two-state: the same read yields 0 (a valid value), so the end marker is never seen and the loop never ends. The fix is to put the row count in word 0 and loop to it.
6. The mutant "the upper clamp triggers at the limit itself" survives. Is the test weak?
Worked answer: no. At the limit the clamped value and the unclamped value are the same number, so the two circuits agree on every input: the mutant is equivalent and no test could separate them. It is reported and set aside, as opposed to the three real gaps in the first version, where an input existed that distinguished the mutant and the test had not tried it.
7. Convert 1100_1010 and 0011_0111 to decimal by hand. What is their sum as an 8-bit pattern, and what does it mean as a signed number?
Worked answer: 1100_1010 = -128 + 64 + 8 + 2 = -54. 0011_0111 = 32 + 16 + 4 + 2 + 1 = 55. The unsigned sum of the patterns is 1_0000_0001; dropping the ninth bit leaves 0000_0001, which is +1, and -54 + 55 = +1 is the correct signed result. The same adder produced it, which is the reason for two's complement.
8. In Running example A, what would the accumulator be after cycle 8 if clr with en = 1 loaded zero instead of the product? Which mutant is that, and what catches it?
Worked answer: 0 instead of 4 after cycle 8, and 100 instead of 104 after cycle 9 (the 10 x 10 product is added to a wrong start). That is the MAC mutant "clr with en loads zero". The golden-model rows that start a sum with clr = 1, en = 1 and a non-zero product catch it; with a x b = 0 the mutant would be invisible, which is why the directed rows use non-zero products.
9. Running example B shows the wrapping MAC reads exactly 0 after 262,144 worst-case products. Why, and why is it worse than garbage?
Worked answer: 262,144 = 2^18 products of 2^14 sum to 2^32, and a 32-bit register holds sums modulo 2^32, so the register reads 0, the same as an empty sum. Garbage would look wrong; this looks plausible and cannot be told from a correct run by inspecting the result. That is the case for saturation (or for proving the sum cannot reach the limit).
Chapter 3
1. Why does the scheme avoid -128, and what would break if it were allowed?
Worked answer: the range -127..127 is symmetric about zero, so negating any value is again in range and requant(-x) = -requant(x) holds. With -128 allowed, -(-128) = 128 does not fit in int8, the magnitude-based hardware would need an extra case, and -128 x -128 = 16384 would be reachable (it is the worst case for the accumulator in Chapter 2). The price is one unused code out of 256.
2. The requantizer rounds the magnitude, not the signed value. What would change for an accumulator of -3 with M = 1/2?
Worked answer: -3 x 1/2 = -1.5, an exact tie. Rounding the magnitude (3/2 = 1.5 rounds away to 2) and restoring the sign gives -2. Rounding the signed value with "add a half then shift" (floor of -1.0) would give -1, so negative ties would round toward +infinity and the result would no longer be symmetric. The mutant "rounding done on the signed value" is caught by the tie cases in the key.
3. Why does the error not grow with K, and why does an outlier column hurt the other columns?
Worked answer: each product has a small independent rounding error; the sum of K errors grows like sqrt(K), but so does the signal for random data, so the relative error stays near 1-1.5%. An outlier column raises the single per-tensor scale (max|w|/127), so ordinary values near 1 map to just a few integer levels and their rounding error becomes large (19.5% measured). Per-column scales give each column its own range (1.3% measured).
4. The mutant "shift of 0 adds a half" survives. Why is that not a test gap?
Worked answer: with s = 0 the expression 1 << (s - 1) evaluates 1 << 63 in a 56-bit wire, which is zero. The mutant therefore computes the same value as the original for every input; no test can distinguish them. It is an equivalent mutant and shows the special case is redundant (dead logic).
5. A 7B-parameter model in int8 needs 7 GB of weights. If a chip can read 100 GB/s, what is the upper bound on tokens per second, and what are you assuming?
Worked answer: 100 GB/s / 7 GB = about 14 tokens per second, assuming every weight is read once per token (batch size 1), nothing is cached on chip, the KV cache and activations are negligible, and the memory system sustains its peak. Batching several sequences reuses each weight read, which is the subject of Chapter 9.
6. Quantize [0.5, -2.0, 1.0, 0.0] by hand.
Worked answer: scale = 2.0 / 127 = 0.015748. Then 0.5 / 0.015748 = 31.75 -> 32; -2.0 -> -127; 1.0 / 0.015748 = 63.5 exactly, a tie, which rounds away from zero to 64; 0 -> 0. Dequantized: 32 x 0.015748 = 0.5039, -2.0000, 64 x 0.015748 = 1.0079, 0. The tie case shows why the rounding rule must be fixed: round-half-away and round-half-even agree here (64 is even), but would differ on a neighbour such as 62.5 (63 versus 62), so the reference and the circuit must use the same rule.
7. Verify m / 2^s for Example A, and say what s = 30 would do.
Worked answer: M = 0.006871868289; m / 2^31 = 0.006871868391; the relative difference is 1.5e-8, below the bound 2^-24 = 6e-8. With s = 30 and the same m, the effective multiplier would be 2M: every output would double (and clamp at +-127), so 77 would become 127 and the whole layer would be saturated. A wrong shift is a gain error of a power of two, which is why the mutation table contains "a shift of 5 bits instead of 6".
8. Why does the per-column error not change with f while the per-tensor error does?
Worked answer: the number that changes is the scale. Per-column, each column's scale is its own max/127, so an outlier in column 0 does not touch column 1's scale. Per-tensor, there is one scale = (largest value anywhere)/127, so the outlier sets the step for every column, and the step grows in proportion to f.
Chapter 4
1. At which cycle does PE(2,1) multiply A[2][3] by B[3][1]?
Worked answer: A[i][k] and B[k][j] meet at PE(i,j) on cycle k + i + j = 3 + 2 + 1 = 6. The wavefront for N=3, K=4 shows PE(2,1) working on A[2][3]*B[3][1] in cycle 6.
2. Derive the number of cycles for a K-long product on an N x N array, and the utilization for N = 4, K = 4.
Worked answer: the last PE, PE(N-1,N-1), starts at cycle (N-1)+(N-1) = 2N-2 and needs K cycles, so the last multiply is in cycle K+2N-3 and the product takes K+2N-2 cycles. Each of the NN PEs does K useful MACs, so utilization = NNK / ((K+2N-2)N*N) = K/(K+2N-2). For N=4, K=4 that is 4/10 = 0.4 (the model prints 0.400).
3. Why does clr also clear the pass-through registers? Which mutants show it?
Worked answer: after a product the last values are still in the registers. If they stay, they are multiplied into the first cycles of the next product. The mutants "clr does not clear the pass-through a register" and "...b register" are caught, but only on the second and later products.
4. A tester runs one matrix product per simulation, starting from reset. Which of the 16 mutants would it miss?
Worked answer: the three clr mutants (accumulator not cleared, either pass-through register not cleared). Registers start at zero in a two-state simulator such as Verilator, so there is nothing stale to clear and these mutants behave like the original on a first product. (In Icarus the registers start as x, so removing the clear would show up as x even on a first product, by reasoning rather than by a run; the safe test is the one the book uses, many products back to back.)
5. A 128 x 128 array multiplies matrices with K = 64. What is the utilization, and what does that suggest about small batches?
Worked answer: 64 / (64 + 254) = 0.201, about 20%. The array spends most of its time filling and draining. It suggests keeping the array busy by making K long, or by streaming several products back to back (without draining between them), or by batching requests, which is Chapter 9.
6. PE(1,2) holds 2 after edge 5 and 3 after edge 6: which products?
Worked answer: after edge t, PE(1,2) holds the sum over k <= t - 1 - 2 = t - 3. With A[1] = [0, -1, 2, 1] and column 2 of B = [2, 0, 1, 1] the products are 0, 0, 2, 1. After edge 5 the sum covers k <= 2: 0 + 0 + 2 = 2. After edge 6 it covers k <= 3: 2 + 1 = 3. Edge 6 is i + j + K - 1 = 1 + 2 + 3, the cycle PE(1,2) finishes.
7. A 4 x 4 array, a 4 x 16 by 16 x 4 product: cycles and utilization; versus sixteen K = 1 products.
Worked answer: one tile with K = 16 takes 16 + 2 x 4 - 2 = 22 cycles; utilization 16 / 22 = 0.727. Sixteen separate K = 1 products each take 1 + 6 = 7 cycles, 112 in all, utilization 1/7 = 0.143, for the same 256 multiply-accumulates. Batching the inner dimension into one product is five times faster here: the fill and drain are paid once instead of sixteen times.
8. Tile (1, 0) of Example B.
Worked answer: tile (r, c) covers output rows 4r..4r+3 and columns 4c..4c+3, so tile (1, 0) uses rows 4..7 of A (a 4 x 8 slice) and columns 0..3 of B (an 8 x 4 slice), each with the full K = 8.
Chapter 5
1. For TILE = 16, LAT = 4, CPW = 2 the model gives L = 23 and C = 35. Compute the serial and double-buffered cycles for T = 6 tiles (with S0 = D0 = 0), and check them against the run.
Worked answer: serial = 6 x (23 + 35) = 348. Double-buffered = 23 + 5 x max(23, 35) + 35 = 23 + 175 + 35 = 233. The run prints exactly serial=348 double-buffered=233.
2. Why can double buffering never give a speedup of more than 2x?
Worked answer: the serial time is about T(L + C) and the double-buffered time about T x max(L, C) (for large T). The ratio (L + C) / max(L, C) is at most 2, reached when L = C. If one side is ten times the other the ratio is 1.1: there is little to hide. (Three-way overlap of load, compute and store can reach 3x, but that is a different design.)
3. Why must a bank be marked empty when the compute finishes and not when it starts?
Worked answer: while the compute is running it is still reading words from that bank. If the bank were marked empty at the start, the DMA could begin writing the next tile into it and overwrite words not yet read, so sums would be wrong. The mutant "a load may overwrite a bank that is still full" is the hazard in a simpler form; it is caught by the compute-bound shape.
4. Which of the two bugs that only one shape caught would also be missed by a testbench that runs only the serial mode?
Worked answer: the overwrite bug. In serial mode a load starts only when nothing is full and nothing is computing, so the !full[nb] guard is redundant there and removing it changes nothing. The bug is visible only in double-buffered mode, and only where the compute is slower than the load. (The "first cycle of the slot" bug shows in serial mode too, as a cycle-count difference, when CPW > 1.)
5. A real DRAM has a latency of about 100 cycles and returns 64 bytes per request. What would you change in the DMA engine so that a tile of 1 KB is loaded efficiently?
Worked answer: request in bursts of 64 bytes (16 requests for 1 KB, each returning many words) instead of one request per 4-byte word; make the engine accept wide data (64 bytes = 16 words) and write it to the scratchpad with a wide write port or several narrow ones; keep enough requests in flight to cover the 100-cycle latency (bandwidth x latency, the bandwidth-delay product); and align tiles to 64-byte boundaries. The engine here issues one single-word request per cycle, which is the right idea at the wrong granularity.
6. TILE = 32, CPW = 2, LAT = 16.
Worked answer: L = 32 + 16 + 3 = 51, C = 32 x 2 + 3 = 67. C > L, so the compute sets the pace. For 16 tiles: serial = 16 x (51 + 67) = 1888; double-buffered = 51 + 15 x 67 + 67 = 1123; speedup 1888 / 1123 = 1.68, which is the value in the table of Running example B (LAT = 16, TILE = 32).
7. LAT = 64, TILE = 16.
Worked answer: L = 16 + 64 + 3 = 83, C = 16 x 2 + 3 = 35; L > C, so the load sets the pace. The break-even is TILE >= LAT / (CPW - 1) = 64: at TILE = 64, L = C = 131; at TILE = 32, L = 99 > C = 67 is still load-bound.
8. Why does load 2 start at 58 and not 46?
Worked answer: tile 2 is loaded into bank 0 (tile n goes to bank n % 2), and bank 0 holds tile 0, which is still being computed on until cycle 57. A bank becomes empty only when the compute on it finishes, so the load cannot start until then. The DMA is waiting for the compute unit because compute (35) is slower than load (23).
Chapter 6
1. Why is subtracting the maximum necessary, and what would the table need to hold without it?
Worked answer: without it the exponent x/16 can be as large as 127/16 = 7.9, so exp reaches about 2,800, and the sum of N such terms needs even more bits; the table would need to hold both large values and small ones (exp of -128/16 = -8 is 3.4e-4), i.e. a wide range at fixed precision. After subtracting the maximum every exponent is in (0, 1], so a 16-bit fraction (65535 = 1.0) is enough, and the largest element contributes exactly 1.0, which keeps the sum at least 65535 (so the division never meets a tiny divisor).
2. How many cycles does a 128-element softmax take on this unit, and what part of that is the division?
Worked answer: 3N + 43 = 3 x 128 + 43 = 427 cycles, by extending the formula, which follows from the structure and was measured only up to N = 64 (the run did not try 128). The division is 40 of the 427 cycles, about 9%; for short rows the division dominates (N=8: 40 of 67).
3. The sum of the probabilities is not exactly 65536. Why, and by how much at most in the study?
Worked answer: each probability is rounded to an integer (Q0.16), and each table entry was already rounded to 16 bits, so the individual errors do not cancel exactly. The worst deviation of the sum from 1.0 in the study was 3.1e-05 at N=8 and 2.1e-04 at N=64 (about 14 units of 2^-16).
4. The divider testbench pulses start in the middle of a division on odd cases. What bug does that catch, and why did the original testbench not?
Worked answer: the bug where start is not ignored while the unit is busy, so a second start restarts the division with new operands (mutant "a start during a division restarts it"). The original testbench only pulsed start while the unit was idle, which is the flow's normal case, so the restart path was never visited; the author confirmed by running the mutant against the old testbench and seeing it pass.
5. The table is zero from d = 189. What does that do to a vector with 200 equal low scores and one high score?
Worked answer: the high score gets e = 65535, and each of the 200 low scores (if more than 11.8 below it) gets 0, so the sum is 65535, r = 2^38 / 65535, and the high score's probability is 65536 (1.0) and every other element's is 0. The true softmax would give the 200 together a mass of up to 200 * 7.4e-6 = 1.5e-3; the unit loses it. That is the intended trade for a 16-bit table, and it only matters if many tiny terms add up to something comparable to the large one. The Chapter 6 study shows the same effect in its largest error (N=64, one big score, 63 small ones).
6. Scores [16, 0] by hand.
Worked answer: m = 16, d = [0, 16], e = [65535, 24109], s = 89,644, r = floor(2^38 / 89644) = 3,066,327; p = [47911, 17625]. As fractions of 65536: 0.73106 and 0.26894, against the real 0.731059 and 0.268941: within 0.4 of a unit of 2^-16. The two sum to 65536.
7. Why is the cycle count independent of the data, and why does it matter?
Worked answer: every pass visits all N elements whatever their values, and the divider always runs W = 40 cycles. So the unit's latency is exactly 3N + 43 for any input, and whoever schedules around it (the sequencer in Chapter 7, the compiler's cycle model in Chapter 11) can budget it without waiting for data. A data-dependent latency (for example a divider that stops early) would force a handshake and make every schedule a distribution instead of a number.
8. Why is the top probability at k = 4 only 0.978?
Worked answer: clipping is not the reason. At k = 4 the scores are [127, 64, 32, 0, ...]; the second score is 63 below the maximum (a real distance of 3.94), so it still has weight exp(-3.94) = 0.019, the third has exp(-5.9) = 0.003, and so on. The top probability is 1 / (1 + 0.019 + 0.003 + ...) = 0.978. To get closer to 1 the scores would have to be farther apart than Q4.4 allows.
Chapter 7
1. MM dst=100 A=0 B=64 M=2 K=5 N=3 tb=1 lda=5 ldb=5 ldc=3: where in the scratchpad is B[k][n] and where is C[m][n]?
Worked answer: with tb = 1, B is stored as N rows of K elements, so B[k][n] is at B + n*ldb + k = 64 + 5n + k. C[m][n] is at dst + m*ldc + n = 100 + 3m + n. (A[m][k] is at 0 + 5m + k.)
2. How many busy cycles does the model give for that instruction? Which part is arithmetic and which is data movement?
Worked answer: M*K + K*N + (K+M+N-2) + M*N + 7 = 10 + 15 + 8 + 6 + 7 = 46 (the calibration table shows 46 measured). Only the streaming term (8 cycles, the K+M+N-2 of Chapter 4) is arithmetic in the array; staging the operands (25 cycles), writing the result (6) and control (7) are data movement and overhead: arithmetic is 8 of 46 cycles, about 17%.
3. Why does the ISA forbid partially overlapping operand regions for SM?
Worked answer: the unit is pipelined: it writes output j while it is still reading later inputs. With identical regions that is safe (output j goes where input j was, already read) and with disjoint regions it cannot interfere, but with a partial overlap an output can overwrite an input not yet read, so the result depends on the pipeline. The reference simulator reads everything first, so the two disagree. The first random-program generator produced such a case and the test failed because of it, not because of a chip bug.
4. A mutant changes the load's source-address field from 16 bits to 12. Why did no test catch it, and what would catch it?
Worked answer: the test's external memory has 2048 words, so every address fits in 12 bits; the upper four bits are always zero in every test. Only a program that addresses external memory above 4095 can tell the two apart, which needs a bigger memory model (and a golden model for it). The mutant is equivalent within the tested range, not in general.
5. Why is the cycle model's constant for MM (7) bigger than the ones for the vector units (2 to 6)? Name two things in ga2_mm.v that it contains.
Worked answer: the matrix unit has more phases, and each phase has a pipeline edge and a state change: after loading A there is a cycle to drain the last read and switch state, the same after loading B, there is the PRE cycle that clears the array, the transition from streaming to storing, and the FIN state that raises done. Any two of these (read off the state machine, not separately measured): the idle cycle between LA and LB, the PRE (clear) cycle, the FIN cycle.
6. Where does the cycle between done and the next fetch go?
Worked answer: the sequencer sees unit_done in WAIT, advances pc and moves to FETCH in the same clock edge; the FETCH state then spends one cycle reading the new instruction word. So the DONE cycle is the last cycle of the unit and the FETCH cycle follows it immediately; what the table calls "FETCH at cycle 23" after "DONE at 22" is simply the next cycle. Over a program, every instruction pays 2 cycles (FETCH and ISSUE) regardless of its unit's work: n instructions cost 2n cycles of overhead, plus 2 for HALT.
7. Busy cycles and the total of Running example B.
Worked answer: ld len=40: 40 + 8 + 1 = 49. mm 4x4x4: 16 + 16 + 10 + 16 + 7 = 65. rq len=16: 18. mm 4x4x2: 16 + 8 + 8 + 8 + 7 = 47. rq len=8: 10. Each amax len=2: 5, four of them 20. st len=4: 6. The sum of busy times is 49 + 65 + 18 + 47 + 10 + 20 + 6 = 215; ten instructions add 2 x 10 = 20 for fetch and issue; the HALT adds 2: 215 + 20 + 2 = 237, the circuit's count.
8. A second ld for W2.
Worked answer: an extra instruction costs 2 cycles of fetch and issue and pays the memory latency again (8 + 1): 11 more cycles in total than the single ld len=40, which pays the latency once. The words themselves cost the same either way.
Chapter 8
1. Why does a decode step need no causal mask?
Worked answer: the cache holds only the tokens generated so far, including the new one. Attention to "later" tokens is impossible because they do not exist yet. A mask is needed when many positions are computed at once (prefill, training), where the rows for later tokens are present in the same matrices and must be hidden.
2. A model has 24 layers, 16 heads of width 64 and an fp16 cache. How many bytes per token and for a 2,048-token context?
Worked answer: per token = 2 (K and V) x 24 x 16 x 64 x 2 bytes = 98,304 bytes (96 KiB). For 2,048 tokens: 98,304 x 2,048 = 201,326,592 bytes = 192 MiB per sequence.
3. In the cached program at L = 32, 12 of the 24 MM instructions do not depend on the context length. Which ones, and what is their total cycle cost?
Worked answer: the projections of the new token: 4 each for q, k and v (output width 16 in blocks of 4, M = 1, K = 16, N = 4). Each costs 16 + 64 + 19 + 4 + 7 = 110 busy cycles plus 2 for fetch and issue = 112, so 12 x 112 = 1,344 cycles, about 26% of the 5,251-cycle step. (The other 12 MMs, the score tiles and the output tiles, do depend on L.)
4. Why does the exact integer reference miss "q requantization scale is 3% too large" while the stage-wise check catches it?
Worked answer: the reference calls rq_params for its scales, just as the builder does, so a bug in rq_params changes both outputs identically and they remain equal. The stage-wise check never calls rq_params: it recomputes each stage from the real-valued meaning of the scales (q should equal the product of the quantized inputs times scale_x times scale_w divided by scale_q), so a 3% error moves some values by several levels, and it reports them.
5. Why can no single-step test catch "the new key is never appended to the cache"?
Worked answer: the append writes the new key to external memory for use by the following step; within the step itself the new key is already in the scratchpad, so the output of this step is the same with or without the append. Only a test that runs a second step reading the cache the first step wrote can see it. That is why sequence() runs whole decode loops with the external memory persisting from step to step.
6. Why 0.297 against 0.291, and what changes at 1/32?
Worked answer: the chip rounds each score to a multiple of 1/16 (scores x 16 as int8): 0.7071 becomes 11/16 = 0.6875, 0.3536 becomes 6/16 = 0.375, 1.0607 becomes 17/16 = 1.0625, -0.7071 becomes -11/16. The softmax of those rounded scores gives 0.2907 for token 0. Chapter 6's integer softmax itself adds only 0.00002. Keeping scores to 1/32 halves the rounding step, so the error of the weights would roughly halve, at the price of an extra bit in the score format and a larger exp table.
7. Cache for 12 layers, 12 heads of width 64, int8, 4,096 tokens.
Worked answer: per token 2 x 12 x 12 x 64 x 1 = 18,432 bytes; for 4,096 tokens 18,432 x 4,096 = 75,497,472 bytes = 72 MiB.
8. Why is the cached step not faster at context length 1?
Worked answer: with one token there is nothing in the cache to reuse, so the cached program does the same projections as the recompute program (one row), plus two extra instructions that append k and v to the cache in external memory (2,500 against 2,460 cycles). The benefit only appears when there are earlier tokens whose keys and values would otherwise be recomputed.
Chapter 9
1. What is GA-2's ridge point, and which side of it is a decode step on?
Worked answer: peak compute is 16 MACs per cycle (a 4 x 4 array) and memory moves 1 word per cycle, so the ridge point is 16 MACs per word. A decode step has about 1 MAC per word (0.98 measured at batch 1), 16 times below the ridge: it is memory-bound.
2. The words moved per step are 768 + 544 B. Where do 768 and 544 come from?
Worked answer: 768 is the three weight matrices (Wq, Wk, Wv) of 16 x 16 words each, loaded once for the whole batch. 544 is what each sequence adds at L = 16: its new hidden state 16, its cached keys and values 2 x 15 x 16 = 480, the two appended rows stored back 2 x 16 = 32 and its output 16: 16 + 480 + 32 + 16 = 544. For B = 4 that is 768 + 4 x 544 = 2,944, as measured.
3. Why does the batch's MAC-per-word figure approach 2.35 but not 16?
Worked answer: per sequence the MACs are 768 for the projections (which reuse the shared weights, so they add no weight traffic) plus 512 for attention, 1,280 in all, against 544 words of that sequence's own traffic, so the limit is 1,280 / 544 = 2.35. Attention uses each cached word once, so it stays at about 1 MAC per word however many sequences are batched; only the projections benefit from sharing.
4. Using the table, at what batch size does the KV cache equal the weights for int8 weights, and what does that say about adding more batch beyond it?
Worked answer: 7.0 GB of weights divided by 1.07 GB of cache per request is 6.5. Beyond a batch of about 6.5 the cache traffic exceeds the weight traffic, so the throughput rises more slowly (from 662 tokens/s at 16 to 908 at 256, against a limit of 931): extra batch mostly adds cache traffic that does not amortize.
5. Why did the first version of the batch test miss "every sequence reads the hidden state of sequence 0", and what fixed it?
Worked answer: the batched step and the single-sequence step are built by the same builder, so both read sequence 0's state for every sequence and agree with each other. The first version compared with the integer reference only for a batch of one, which means only sequence 0, whose state is the correct one. Comparing every sequence, decoded alone, with the integer reference makes the single run for sequences 1 to 3 wrong, and the mismatch appears.
6. The maximum batch of 33 on chip B at 8,192 tokens.
Worked answer: capacity is 80 GB; the weights take 7 GB, leaving 73 GB. One request's cache is 256 KiB x 8,192 tokens = 2 GiB = 2.147 GB. 73 / 2.147 = 33.99, and a batch must be a whole number of requests that fit, so 33 (a 34th would need 71.1 GB of cache and 78.1 GB in all, over the 80 GB with no room for anything else).
7. Slots spent by static batching on lengths 14, 3, 9, 5.
Worked answer: the group runs 14 steps with four slots: 14 x 4 = 56 sequence-slots. Only 14 + 3 + 9 + 5 = 31 are useful; 25 slots (45%) are spent on requests that have already finished.
8. The best fraction of peak for attention-dominated decoding.
Worked answer: with memory delivering one word per cycle, the highest attainable rate is intensity x 1 = 2.35 MACs per cycle at L = 16, against a peak of 16: 2.35 / 16 = 14.7%. The circuit reaches 0.33 to 0.61 MACs per cycle (2% to 4% of peak), because instructions also do not overlap.
Chapter 10
1. Why does the toy library come with two files generated from one table?
Worked answer: synthesis reads the Liberty file (functions, areas, delays) while simulation reads Verilog models of the same cells. If a function differed between them, the netlist would be wrong with respect to its own simulation models in a way no tool would warn about. Generating both from one table removes the possibility; the mutation run then breaks it on purpose to check that simulation would notice.
2. The critical path of the chip is sp.rdata -> ... -> sp.wdata. Which unit is on it, and what would you change?
Worked answer: the requantizer, inside the RQ unit: it sits between the scratchpad's read data and its write data, 79 gates deep (9.87 ns). Pipelining it, i.e. a register in the middle of the 32 x 24 multiplier, so that RQ takes two or three cycles per word, would shorten the clock period to about that of the next-slowest units (5-6 ns in this model); the cost is a larger constant in the cycle model for RQ.
3. What is X-pessimism, and what evidence shows that the Icarus failure was not a logic error?
Worked answer: a four-state simulator propagates x through logic that, after optimization, no longer simplifies it away (as in (a & b) | (a & ~b) with b = x); real flip-flops would hold a definite 0 or 1. Evidence it was not a logic error: the same netlist passes in Verilator (two-state), passes in Icarus when the flip-flop model gives a defined power-up value, and passes in Verilator from three random power-up states, with identical memory and cycle counts every time.
4. Why did the first random power-up run produce deadbeef in the data, and who was at fault?
Worked answer: in the first clock the chip's random power-up state made it issue a memory request before reset took effect; the testbench's memory answered it eight cycles later (with its out-of-range pattern) just as the real first load began, so the first word of the data was wrong. The testbench was at fault: its memory model did not discard in-flight requests at reset, which a real system's reset would do.
5. What does it mean that 3 faults were "proven redundant", and why is detecting them not a goal?
Worked answer: for those faults the equivalence checker proved that the faulty circuit computes the same function as the good one (under the operating constraint), so there is no input at all on which they change an output. They cost nothing functionally and cannot be detected by any test. Fault coverage is therefore quoted over the testable faults (here 297, not 300).
6. Shortest clock period for the path.
Worked answer: 0.30 (clock-to-q) + 0.07 + 0.16 + 0.11 + 0.04 (the four gates) + 0.10 (setup) = 0.78 ns, so at most 1 / 0.78 ns = 1.28 GHz in the toy library. Any slower path elsewhere would set the clock instead.
7. A 3.2x faster adder that is 20% of the critical path.
Worked answer: if the adder is 20% of the path's delay, the new path is 0.8 + 0.2 / 3.2 = 0.8625 of the old, so the clock can be 1 / 0.8625 = 1.16x faster. Speeding up a part helps in proportion to the fraction of the path it occupies (Amdahl's law applied to a path). In the requantizer the adders are a much larger fraction, which is why the same change helped there.
8. Why the first cut gave only 11%.
Worked answer: the clock is set by the slower stage. After cutting after the multiplier, stage 1 (the multiplier, 8.23 ns) and stage 2 (the rounding adder, shift and clamp, 8.39 ns) were almost equally long, both near the old whole-unit time of 9.87 ns less the savings from splitting; adding the register's 0.4 ns of clock-to-q and setup left 8.90 ns. Pipelining only pays when the cut divides the delay evenly, and here stage 2 was long because of a ripple adder, which has to be replaced to make the cut worth it.
Chapter 11
1. Why does the compiler reject a matmul with K = 65, and what would the hardware need to support it?
Worked answer: the matrix unit's operand memories hold 64 values per row and column, and one MM instruction computes a whole inner product. A longer inner dimension would have to be split into two products whose int32 results are added, but the ISA has no instruction that accumulates int32 values (VADD is a saturating int8 add), so the compiler cannot express it and refuses. Supporting it needs an accumulate flag on MM (or an int32 add) so partial sums can be combined before the single requantization.
2. Why was forcing both operands of an add to share a scale wrong, and what does the compiler do instead?
Worked answer: when one operand is pinned (a softmax output is always 1/127, a range of 1.0) the shared scale cannot hold an operand that reaches 3, so that operand saturated and the output was 50-100% wrong. The compiler now gives the sum its own scale, covering both operands and the sum, and inserts an RQ (int8 to int8, multiplier scale_operand / scale_sum) on each operand whose scale differs.
3. Why is check (c) run with buffer reuse switched off?
Worked answer: with reuse, a tensor's space is given to later tensors, so after the program ends its original location holds something else and cannot be read back for comparison. With reuse off, every tensor keeps its own buffer to the end, so each can be compared with the interpreter. Check (a) separately ties the reuse version to the no-reuse version.
4. Which check catches "buffers are released one step too early", and why do the others not?
Worked answer: (a). The no-reuse program is correct and the reuse program overwrites a live buffer, so their outputs differ. (c) runs with reuse off, so it never exercises freeing; (b) compares the no-reuse run with the interpreter; (d) and (e) also read the no-reuse run or only judge scales and accuracy.
5. Why is the cancellation graph tested without an accuracy bound, and what bug does it exist to catch?
Worked answer: with y near -x the sum is tiny, and an int8 sum at a scale that holds the large operands rounds it to about zero, so even the correct compiler is far from floating point there. The graph exists to catch a compiler that picks the sum's scale from the sum alone: the rescaled operands then clip, and the sum of the clipped values is far from the real-number result, which check (d) reports. Random graphs almost never contain a cancellation, so only a directed case reveals that bug.
6. Why the scores' scale is 0.0625 and not 0.0201.
Worked answer: the softmax unit's input is defined as the score times 16 stored in an int8 (Q4.4), so the scale of the tensor feeding it must be exactly 1/16 = 0.0625. With scale 0.0201 the integers would mean three times larger real values than the softmax unit assumes (0.0625 / 0.0201 = 3.1), the exponentials would be those of the wrong numbers, and the probabilities wrong. The price of pinning is range: the scores can only reach 127/16 = 7.9 before they saturate, which the compiler checks and reports as a note.
7. The MM instructions for 5 x 12 times 12 x 10.
Worked answer: ceil(5/4) x ceil(10/4) = 2 x 3 = 6 instructions: (M, N) = (4, 4), (4, 4), (4, 2) for rows 0-3, and (1, 4), (1, 4), (1, 2) for row 4. All have K = 12, lda = 12 (the row length of A), ldb = 10 (the row length of B) and ldc = 10 (the row length of C).
8. Why width 64 fails even with reuse.
Worked answer: the second layer's weight matrix is 64 x 64 = 4,096 words, the whole scratchpad. The compiler must hold it together with the activations that feed and leave the product, so it cannot fit. At width 48 the same weight is 2,304 words, leaving room. A model that does not fit must be split into pieces (the compiler has no spilling; the page lists this as not covered).
Chapter 12
1. The model's next token is f(t) = (5t + 3) mod 16 although attention and the feed-forward block are running. Why does the output not depend on them, and what does that imply for what this test can show?
Worked answer: the embeddings are orthogonal and the output projection is arranged so that the logit of f(t) is about 8 for the current token t and near 0 for the others; attention and the feed-forward block add small terms (7% and 14% of the embedding's norm) that change the logits' detail but not the winner. The test therefore shows that the pipeline (compiler, scales, cache, instructions, chip) computes the graph correctly, because the token and the logits come out as in floating point; it cannot show that attention matters to the model's answer, nor how good the model is.
2. A decode step costs 7,000 cycles at context 1 and 9,039 at context 24. What does the 7,000 consist of, and what would batching change?
Worked answer: the part that does not depend on context: loading about 2,304 words of weights (the four attention matrices, the two feed-forward matrices and the output projection) and multiplying the one new row by them (the matrix unit's staging dominates because M = 1). Batching several requests would load the weights once and run each projection with M equal to the batch, so the per-token cost of this part would fall roughly in proportion; the 2,000 context-dependent cycles (cache loads and attention) would not.
3. The chip agrees with floating point on 97% of the random model's decisions. Why is the agreement not 100%, and what would you measure on a trained model?
Worked answer: int8 per-tensor quantization introduces about 2% relative error in the logits; when the two best logits are closer than that error the chip may pick the other one, which happened in 17 of 576 decisions. On a trained model the right measures are task-level: the change in perplexity or accuracy on held-out data, and the agreement of generated text, not agreement with a random model's argmax.
4. The capstone catches 38-39 of the 49 hardware mutants and Chapter 7's suite catches all of them. Name two mutants the capstone misses and say why they are not bugs for programs the compiler writes.
Worked answer: for example "A's row step uses K instead of lda" and "C's row step uses N instead of ldc": the compiler always emits lda = K and ldc = N (dense matrices), so the mutant computes the same addresses. Another: "VADD upper clamp is 126": the residual sums in this model never reach 127, so the clamp never acts. (Also acceptable: the field-width mutants, since the compiler never emits K = 64 or M = 4 in a decode step.)
5. Which tests in this book would you rerun first after changing the compiler's tiling, and which after changing the requantizer's RTL?
Worked answer: for the tiling, the compiler's battery of Chapter 11 (the interpreter and every-tensor checks) and then the capstone; for the requantizer RTL, Chapter 3's 201,808-vector comparison and mutation run, then Chapter 7's program suite (which uses RQ) and, since the requantizer is the chip's critical path, the gate-level checks of Chapter 10.
6. The first four tokens of each rule.
Worked answer: for f(t) = (5t + 3) mod 16 starting at 0: 5 x 0 + 3 = 3; 5 x 3 + 3 = 18, mod 16 = 2; 5 x 2 + 3 = 13; 5 x 13 + 3 = 68, mod 16 = 4: so 0, 3, 2, 13, 4. For f(t) = (3t + 7) mod 16: 7; 3 x 7 + 7 = 28, mod 16 = 12; 3 x 12 + 7 = 43, mod 16 = 11; 3 x 11 + 7 = 40, mod 16 = 8: so 0, 7, 12, 11, 8. Both match the closed forms in the run outputs.
7. Would a logit error of 5.0 change the decision?
Worked answer: the margin between the winner (+7.82) and the next logit (+0.5) is about 7.3. If each logit can be wrong by 5.0, their difference can be wrong by up to 10, which exceeds the margin, so the decision could flip. With the measured error of 0.05 the difference moves by at most 0.1, 1.4% of the margin. A decision is safe when the margin exceeds twice the largest error on a logit; this model has a wide margin, which is why int8 is safe here and why the generic random model (small margins) flips about 3% of the time.
8. Why fix the KV cache's range from outside?
Worked answer: each decode step is a separately compiled program, and without ranges= each would calibrate its own scale for k and v from its own context length. The host stores the cache as the dequantized values the chip returned and re-quantizes it with the next program's scale; if that scale changed from step to step, every step would re-round every cached row at a different resolution and the scale would depend on the length of the context. Fixing one range for the k and v tags (taken over all steps in calibration) gives every program the same scale for the cache.
Chapter 13
1. Why -7 .. 7, not -8 .. 7?
Worked answer: the range stays symmetric, so negating a weight never overflows (-(-8) has no 4-bit representation), a single scale works for both signs, and zero stays exactly zero with the same step on both sides. The cost is one unused code out of sixteen (6% of the range).
2. Scale for max|w| = 0.7; what is w = 0.33?
Worked answer: scale = 0.7 / 7 = 0.1. 0.33 / 0.1 = 3.3, which rounds to 3; the dequantized value is 0.3 and the error is 0.03, below half a step (0.05).
3. Pack [1, -1, 2, -2, 3, -3, 4, -4].
Worked answer: the nibbles of elements 0..7 are 1, F, 2, E, 3, D, 4, C. Element 0 is the least significant nibble, so reading from the most significant end the word is C 4 D 3 E 2 F 1 = 0xC4D3E2F1.
4. Where do the 10 cycles of UNPACK come from?
Worked answer: one cycle to issue the read, one for the scratchpad's read latency (the data is latched), and eight writes, one per output element. The scratchpad has a single write port, so eight values cannot be written in fewer than eight cycles; 10 is therefore 8 plus the fixed overhead of 2.
5. Derive b* = 7/u.
Worked answer: int8 takes n/b cycles. int4 takes n/(8b) for the link plus (n/8)u for the unpack. int4 wins when n/b > n/(8b) + nu/8. Multiply by 8b/n: 8 > 1 + ub, so ub < 7 and b < 7/u.
6. Why 2.85x less traffic and not 8x?
Worked answer: only the weights are packed. The model has 2,304 weights (Wq, Wk, Wv, Wo: 4 x 256; W1 and W2: 2 x 512; Wout: 256). At step 24 the total is 3,105 words with int8 weights, so 3,105 - 2,304 = 801 words are not weights (the input, the cache and the outputs). With int4 the weights take 2,304 / 8 = 288 words and the total is 288 + 801 = 1,089, a factor of 2.85. The 801 words did not shrink.
7. Why does the designed model survive int4 and the random model not?
Worked answer: the designed model's answer is fixed by large, well-separated logits (Chapter 12 measured the gap between the best and second-best), so noise of 15-20% cannot reorder them; the random model's logits are close together, so the same noise changes the argmax in 9% of the decisions.
8. Why does a per-column scale need a different requantizer?
Worked answer: the product x W accumulates in integers; each output column j is multiplied by scale_x * scale_Wj to return to real values. With one scale per tensor, one multiplier and shift (the RQ instruction's m and s) serve every column; with per-column scales the multiplier differs by column, so RQ would need a vector of multipliers or one RQ per column.
Chapter 13 -- hints for the exercises
- Uniform weights have no tails, so the largest weight is only 1.7x the standard deviation instead of about 3x: fewer codes are wasted on rare large values.
- Per-column is unaffected by any number of outlier columns; per-group-64 equals per-column here (64 rows = one group per column).
- Measure each matrix alone (one at a time) and rank the logit errors; the matrices whose outputs feed the residual stream most directly usually matter most.
- Two outputs per cycle gives 1 + 1 + 4 = 6 cycles per word; the break-even becomes 7/6 = 1.17 words per cycle, still only a little above this chip's 1 word per cycle.
- Make several int4 weights of about 1,400 elements each (they need 175 staging words each) so that without release the staging areas plus the weight buffers exceed 4,096 words.
- One multiply and one add (or one multiply of the dequantized outputs) per output element: 32 extra operations for a 1x32 result; the result equals the dequantized per-column study up to the requantizer's own rounding.
Chapter 14
1. Head 5 with H = 8, G = 2; cache words for head width 16.
Worked answer: each group serves H / G = 4 heads, so head 5 reads group 5 // 4 = 1. The cache per token is 2 * G * d words: with d = 16 that is 2 * 8 * 16 = 256 words for G = 8, 64 for G = 2 and 32 for G = 1.
2. Why split the output projection into per-head slices?
Worked answer: [a0 a1 a2 a3] Wo has entry j equal to the sum over all 16 positions of a_i Wo[i][j]. Splitting the positions into four blocks of 4 gives four partial sums, a_h times the rows of Wo belonging to head h, and their total is the same number. Capra has no column concatenation or slice, but it has matmul and add.
3. Why are Wk and Wv smaller under GQA?
Worked answer: they produce one key and value of width d per group, not per head: D x (G*d) instead of D x (H*d). The query side (Wq, Wo) keeps all H heads and does not change.
4. Pooling independent against similar heads.
Worked answer: the pooled key is the mean of the heads' keys. If the two heads are independent, the mean is a third, different vector that matches neither (its scores correlate with each head's scores only about 0.7 at best, and with random weights much less usefully), so the attention patterns change. If the heads are nearly equal, the mean is nearly each of them and nothing changes. At eps = 0 the mean of equal vectors is the vector itself, so the conversion is exact.
5. Why do matrix cycles fall with G?
Worked answer: each group needs a key projection and a value projection (matmuls of the new token with Wk and Wv); fewer groups mean fewer such projections (the MM count falls from 56 to 52 to 50) and a smaller requantization workload. The query, score, context and output matmuls of the four heads do not change.
6. 256 KiB and 64 KiB per token.
Worked answer: MHA: 2 (K and V) * 32 layers * 32 heads * 128 values * 1 byte = 262,144 bytes = 256 KiB. GQA with 8 groups: 2 * 32 * 8 * 128 = 65,536 bytes = 64 KiB.
7. Why did the float-step "no 1/sqrt(d)" mutant survive the first run?
Worked answer: the mutant changed the float reference only, while checks 1 and 3 compare the float model with itself (or with a rule that attention hardly influences), and check 2 compares the chip's logits with float through a 15% bound that attention's small contribution does not exceed. Only an independent reference step (check 5), or a tensor-level comparison (check 7), disagrees.
8. Why is a 15% logit bound not enough?
Worked answer: logits are dominated by the residual path and the output matrix; the attention output is a small part of them. A wrong attention changes the logits by less than the bound, so the check passes while attention is wrong. The remedy is to compare the attention output itself.
Chapter 14 -- hints for the exercises
- Group the heads as
h // 4,h // 2,hfor G = 2, 4, 8; the structured rule is decided by the embeddings and Wout, so it should still hold. - Re-solve
Woon the pooled model so thatWo_new = argmin |A_pooled Wo_new - A_mha Wo|over a batch of activations; the normal equations are small (16 x 16). - Int4 activations halve the 64 KiB to 32 KiB for G = 8, but the chip has no int4 matrix operand: the activation path would need the operand-path unpacking of Chapter 13's last section.
- Raise a
CompileError-style error whenH % G != 0; the test builds the graph withG = 3and expects the refusal. - Calibration range of
v: halve it. If the checks still pass, either the effect is below the 12% bound (a gap in the check) or the compiler clamps to the range (then equivalent).
Chapter 15
1. 9 rows, pages of 4.
Worked answer: ceil(9 / 4) = 3 pages; they hold 12 rows, so 3 are unused (all in the last page).
2. The next step's first row; releasable pages for W = 6, L = 8.
Worked answer: step L + 1 attends the new token and the W - 1 before it, so it needs rows from (L + 1) - W upward. For W = 6 and L = 8 that is row 3 (it needs rows 3-7 plus the new one). A page is released only if it lies entirely below row 3; page 0 holds rows 0-3, which includes row 3, so nothing can be released yet. (After step 9 the first needed row is 4 and page 0 can go.)
3. Why reuse freed pages?
Worked answer: a pool has a fixed number of physical pages. If freed pages were not reused, a request that keeps releasing pages at the front and taking pages at the back would use up the pool even though it holds only two pages at any moment. Reuse is what makes the window's bound on memory real.
4. A shared page when one owner finishes.
Worked answer: the reference count falls from 2 to 1; the page stays allocated because the other request still reads it. When the second finishes the count reaches 0 and the page is put on the free list.
5. Why copy-on-write?
Worked answer: two requests with a common prefix share the page that holds its tail; if one appends into the free space of that page without copying, the other request's rows (at the same logical positions) change under it. Copying first gives the writer a private page and leaves the other request's data untouched.
6. Why W programs, not one per step?
Worked answer: a compiled program is specific to the context length n of the step (the cache inputs have n - 1 rows). With a window, n = min(L, W) takes only the values 1..W; every later step reuses the program for W. That saves compile time and program memory (and, for the chip, the programs never grow).
7. Why did a bound miss the two wasteful mutants?
Worked answer: both keep a few more rows or pages than needed. The data they return is correct and the page count stays at or below the loose bound that allows one spare page, so a check on the bound passes. Only a check of the exact expected count can distinguish a leak of one page from correct behaviour.
8. The 87.5% waste.
Worked answer: the contiguous scheme reserves 2,048 rows for each of 4 requests = 8,192 rows, of which the requests actually use 1,022. The waste is (8,192 - 1,022) / 8,192 = 0.875.
Chapter 15 -- hints for the exercises
- Reserved rows are
pages * page; with a window of 8 and 32 steps the final request holds 7 rows: page 1 reserves 7, page 2 reserves 8, page 8 reserves 8, page 16 reserves 16. The block table is longest for page 1. - Admit if
free_pages * page >= expected_len; count the requests that later raiseOutOfPages. - Gather rows
[0, 1] + [L - W + 2 ... L - 2]; the context is stillWrows so no new program is needed. - Pad with dummy rows up to the next multiple of the page size before forking; account for the padding as waste.
- Reverse the order of pages in
trim:rows()would then read the wrong pages: the shadow comparison should catch it; if it does not, add a case.
Chapter 16
1. Guesses [7, 2, 5], choices [7, 2, 9, 4].
Worked answer: guess 0 (7) equals choice 0, guess 1 (2) equals choice 1, guess 2 (5) differs from choice 2 (9). Two guesses are accepted. The emitted tokens are the accepted guesses and the target's choice at the first disagreement: [7, 2, 9]. The cache rows kept are rows 0, 1 and 2 of the block (the rows of the last committed token and the two accepted guesses); row 3, which saw the rejected guess, is dropped.
2. Why the output does not depend on the draft; what a poor draft cannot break.
Worked answer: each emitted token is a guess the target itself chose at that position, or the target's own choice, and each was computed from a prefix of already-accepted tokens, so the sequence is the target's greedy sequence. A poor draft only reduces the number of accepted guesses per block. The argument would break if the verifier let a row see a guess that was later rejected (a non-causal block): then a row's choice would depend on a token that is not in the output.
3. k = 4 and 100% acceptance; why not k = 5?
Worked answer: each block yields k + 1 = 5 tokens, so 32 tokens need 7 blocks (35 tokens, 3 are overshoot). In Example B k = 5 yields 6 tokens per block and needs 6 blocks (36 tokens), and the verifier's cost grows with the rows, so the gain from one more guess is smaller than the loss from the overshoot and the wider verifier. k = 3 gives 4 tokens per block: 8 blocks, exactly 32 tokens, no overshoot.
4. Why a view, and why no concatenation?
Worked answer: a slice of rows is a contiguous range of the source's buffer, so its address is the source's address plus an offset; nothing needs to be copied. A concatenation needs its inputs placed next to each other in one buffer; a slice lives inside its source's buffer, which fixes its place, so it cannot also be placed next to another tensor (that would require a copy, which the compiler does not do for views).
5. Expected tokens for k = 2.
Worked answer: a block always yields 1 token (the target's choice at the first disagreement or after the last guess). The first guess is accepted with probability a, giving a second token; the second is accepted with probability a squared (both must be right), giving a third. By linearity of expectation E = 1 + a + a squared.
6. a = 0.8, k = 4, c = 0.05.
Worked answer: E = (1 - 0.8^5) / (1 - 0.8) = (1 - 0.32768) / 0.2 = 3.36. The cost of a block is 1 + 4 * 0.05 = 1.2 target steps. Speedup = 3.36 / 1.2 = 2.80.
7. Why a sharp-attention model for the causality test?
Worked answer: in the structured model the attention scores are tiny, so the attention weights are nearly uniform over the visible rows and the output barely depends on which rows are visible; a change to a later token in a non-causal block would change a row's output by less than the integer rounding. Multiplying the query and key weights by 4 makes the attention patterns peaked so that a row's output depends strongly on the rows it can see.
8. Why did "bonus token not appended" survive, and what caught it?
Worked answer: if the bonus token is dropped, the next block starts from the last accepted guess instead; the verifier recomputes the target's choice after it, which is the very token that was dropped. The output tokens are the same; only a block was wasted. The check that finally caught it is the accounting one: tokens emitted must equal accepted guesses plus the number of blocks, and the cache length must equal the tokens emitted.
Chapter 16 -- hints for the exercises
- A 256-entry table indexed by (previous token, token before it):
Wdcannot represent it with one embedding, so the draft becomes a lookup done on the host; measure acceptance only, or give the draft a two-token embedding. - Compute
E,t_draftandt_verify(k + 1)for each k and take the maximum ofE * t_plain / (k * t_draft + t_verify); compare it with the measured grid. - With two alternatives for the first guess the verifier needs the rows of both chains; each row sees the cache, the shared prefix and only its own chain, which is a list of row ranges, not a prefix. Capra's
slice_rowsgives contiguous ranges only; you would concatenate the visible pieces, which costs copies. - Accept with probability
min(1, p_target(x) / p_draft(x)); on rejection sample frommax(0, p_target - p_draft)normalized. This keeps the distribution of the output equal to the target's. - Try making the draft's argmax tie-break differently (lowest index versus highest): the output cannot change, so the tests cannot catch it; it is an equivalent mutant for exactness and a quality difference for the acceptance rate.
Chapter 17
1. Why two programs, and what does the host do between them?
Worked answer: the chip executes a fixed instruction sequence; it has no branch, so a program cannot choose which expert's weights to use depending on a value it computed. Program A computes the router's choice and writes it out (with h). The host reads the choice, picks the compiled program of that expert and starts it with h as input.
2. Why does a wrong expert give the input token?
Worked answer: each expert has hidden units that fire only for the four tokens of its own group. A token of another group fires none of them, so the expert outputs about zero, y = h stays equal to the token's own embedding, and the output matrix (which reads embeddings) gives the highest logit to the token that was just given.
3. Why do all the B programs cost the same?
Worked answer: cycle counts depend on the shapes of the matrices and the instruction sequence, which are identical for the four experts (same sizes, same instructions); only the weight values differ. A difference would need different expert sizes, a different number of rows, or different instruction sequences.
4. Distinct experts for B = 4, E = 8.
Worked answer: 8 * (1 - (7/8)^4) = 8 * (1 - 0.586) = 3.31.
5. Why not 50%?
Worked answer: eight separate programs each pay the fixed cost of a program (loading the weights, the output matrix and the fetch and halt); four grouped programs pay it four times, plus the cost of the additional rows. The grouped cost is 4 fixed + 8 rows' worth of arithmetic, so it is more than half of 8 fixed + 8 rows' worth.
6. Why is a flipped route a bigger error than a flipped rounding?
Worked answer: a rounding error changes a logit by a fraction of a step. A flipped route replaces the whole function that processes the token (a different expert with different weights), so the output can change completely; on the structured model it changes the predicted token for sure.
7. Why is top-1 without a gate acceptable here but not for training?
Worked answer: here nothing is trained and the decision is what matters. In training, the gate (the router's probability multiplying the expert's output) is the path by which the loss sends a gradient to the router; without it the router would get no learning signal.
8. Why did the output tests miss the wrong memory image?
Worked answer: the outputs come from running the reference simulator with the correct h; the record kept for the RTL replay is built separately, and a replay of a self-consistent but wrong image passes (the RTL agrees with the reference run on the wrong data). Only a check that compares the image with the h that program A produced sees the difference.
Chapter 17 -- hints for the exercises
- Take the two best router scores; run B for both experts and add their
h-relative outputs on the host (or build a B with two experts); expect about 2x the expert-stage cost. - Multiply
Wrby 0.2: the winner's score falls to about 0.4 and the others to about 0.1, close to the int8 step; look for flips at the 0.2-0.1 range. - Count, per expert, tokens beyond the second; those are dropped (the residual passes through unchanged).
- For
E = 8each expert has two tokens; the touched-experts formula is8 (1 - (7/8)^B). - Calibrate with a start set that never reaches one expert so that the fallback runs; check whether the program still compiles and follows the rule.
Chapter 1 (additional questions)
6. In the ripple example the sum bus shows 6, 4, 0, 8 after 7 + 1. Why are there wrong values at all, and how long after the inputs change is the answer valid?
Worked answer: every full adder computes its sum from the carry it sees now, and the carries have not yet arrived: at the first instant all carries are still 0, so the sum bits are those of 0111 + 0001 without carries, giving 0110 (6). Then carry 1 reaches stage 1 and the sum becomes 0100 (4), carry 2 reaches stage 2 (0000), and carry 3 reaches stage 3 (1000 = 8). With a 1 ns delay per full adder the answer is valid 4 ns after the inputs change: three carry hops plus the last stage's own delay.
7. Why do clocked blocks use <= and not =? What goes wrong in a design with two registers that swap their values (a <= b; b <= a;) if you write =?
Worked answer: non-blocking assignments sample every right-hand side with the values from before the clock edge and update all the registers together afterwards, as real flip-flops do. With a = b; b = a; the first statement overwrites a immediately, so the second copies the new a, and both registers end up holding the old b: the swap is lost. With <= both read the old values and the registers really exchange them.
8. The asynchronous-reset mutant of the counter is caught only because the testbench checks wrap. Explain why a test that checked only q after the clock edge would have missed it.
Worked answer: the testbench raises rst in the middle of a cycle and samples q after the next rising edge. By then both the synchronous circuit (which resets at the edge) and the asynchronous one (which reset earlier) show q = 0, so they look identical. They differ only in when q changed, which is visible in the combinational output wrap = en && q == 15: in the asynchronous circuit it drops immediately when rst rises, in the synchronous one it stays until the edge. Only a check of wrap before the edge sees the difference.
Chapter 1 -- hints for the exercises
- 65,536 x 2 = 131,072 cases: still exhaustive and still fast; the 8-bit settling time in the delayed model would be 8 stages' worth.
- A decade counter's wrap condition is
q == 9; mutants worth adding: wraps at 10, wraps at 15 (not changed from the original), reset loads 9. - A reasonable priority is rst, then load, then en; the mutants are each swap of that order, and a missing
loadcase. - For the 8-bit-input adder there is no input that is not tested; for a 16-bit adder with 1,000 random cases, a mutant that breaks only when
a == 16'hFFFF && b == 16'h0001is untouched by random testing with overwhelming probability.
Appendix A
1. Build XOR from NAND gates only and count them. Check it on all four inputs by hand.
Worked answer: XOR(a, b) = NAND(NAND(a, n), NAND(b, n)) with n = NAND(a, b): four NAND gates. For a = 0, b = 1: n = 1; NAND(0, 1) = 1; NAND(1, 1) = 0; NAND(1, 0) = 1 = 0 XOR 1. The other three inputs check the same way.
2. How many input combinations must a test cover to check a full adder exhaustively? A 16-bit adder with carry in?
Worked answer: A full adder has three inputs, so 2^3 = 8 combinations. A 16-bit adder with carry in has 16 + 16 + 1 = 33 input bits: 2^33, about 8.6 billion combinations, which is why exhaustive testing stops being reasonable beyond about 20 input bits, and why Chapter 1 uses random and directed tests together.
3. In the shift register example, what is the register after three edges for the input stream 1, 1, 0 starting from 0000?
Worked answer: Starting from 0000 with the input stream 1, 1, 0: after the first edge 0001, after the second 0011, after the third 0110.
4. Give the state table of a Moore machine that outputs 1 when the last two bits were both 1 (overlap allowed). How many states does it need?
Worked answer: Three states: S0 (the last bit was 0, or nothing yet), S1 (the last bit was 1 and the one before was not), S2 (the last two bits were 11; output 1). S0: on 0 -> S0, on 1 -> S1. S1: on 0 -> S0, on 1 -> S2. S2: on 0 -> S0, on 1 -> S2 (overlap: the last 1 can start or continue a run).
5. A path has clock-to-q 0.3 ns, logic 3.4 ns and setup 0.1 ns. What is the fastest clock? What happens if you clock it faster?
Worked answer: The period must be at least 0.3 + 3.4 + 0.1 = 3.8 ns, so the fastest clock is about 263 MHz. If it is clocked faster the data has not arrived when the second flip-flop samples it (a setup violation): the flip-flop captures a wrong or undefined value, and the circuit gives wrong answers.
6. Why can a flip-flop's d change between edges without changing q?
Worked answer: The flip-flop only looks at d at the rising clock edge; between edges its output q is held by the stored bit, not by d. That is the whole point of the synchronous style: the combinational logic may glitch and settle between edges without disturbing anything.
Appendix B
1. Write a module inc4 that adds 1 to a 4-bit input with wrap-around, once with assign and once with always @*.
Worked answer: assign y = x + 4'd1; (4-bit arithmetic wraps naturally) and always @* y = x + 4'd1; with output reg [3:0] y. Both are combinational; the second uses a blocking assignment.
2. Why does always @* case (sel) 0: y = a; 1: y = b; endcase for a 2-bit sel produce a latch?
Worked answer: For a 2-bit sel there are four values but only two cases are listed. When sel is 2 or 3 the output must keep its old value, which needs memory, so synthesis builds a latch. A default branch (or an else) assigns the output on every path and removes it.
3. In swap_blocking, what are the values of a and b after the first clock edge following reset?
Worked answer: After reset a = 1, b = 2. At the first edge, a = b makes a equal to 2 at once, then b = a reads the new a and also becomes 2: both registers hold 2 and stay equal.
4. Convert the 4-bit binary values 0110 and 1011 to Gray code by hand. Check that they differ from their neighbours in one bit.
Worked answer: 0110 ^ 0011 = 0101; 1011 ^ 0101 = 1110. Neighbours: 0111 (7) gives 0100, which differs from 0101 in one bit; 1010 (10) gives 1111, which differs from 1110 in one bit.
5. What does {{4{x[7]}}, x} produce for x = 8'h7F? For x = 8'h80?
Worked answer: For x = 8'h7F it produces 12'h07F (the top bit is 0, so four zeros are added); for x = 8'h80 it produces 12'hF80 (the top bit is 1, so four ones are added; -128 stays -128).
6. Why does the book run every testbench in two simulators?
Worked answer: The two simulators were written independently and schedule events differently. A race in the testbench or a construct that is simulator-specific behaves differently in them, so a difference exposes the problem, while a bug that both share is still a bug in the design.
Appendix C
1. Write -37 in 8-bit two's complement. Add 100 to it by hand in binary and check the result.
Worked answer: 37 = 00100101; invert: 11011010; add one: 11011011 (0xDB). Add 100 = 01100100: 11011011 + 01100100 = 1 00111111; dropping the carry out gives 00111111 = 63 = -37 + 100.
2. What do the 8-bit patterns 0x80, 0xFF and 0x7F mean as unsigned and as signed?
Worked answer: 0x80: unsigned 128, signed -128. 0xFF: unsigned 255, signed -1. 0x7F: 127 both ways.
3. Which format represents a value near 0.001 more finely: Q1.7, or fp16? Which represents 1000?
Worked answer: fp16 represents 0.001 much more finely (its spacing near 0.001 is about 1e-6, while Q1.7's step is 0.0078, which would store 0.001 as 0). Only fp16 can represent 1000 at all (Q1.7's range is -1 to 0.99; fp16's spacing near 1000 is 0.5).
4. Round 2.5, 3.5 and -2.5 by truncation, half up and half even.
Worked answer: 2.5: truncate 2, half up 3, half even 2. 3.5: 3, 4, 4. -2.5: truncate -2, half up -2, half even -2 (half away from zero would give -3).
5. How many bits does the sum of 1,000 int8 products need in the worst case?
Worked answer: 16 + ceil(log2 1000) = 16 + 10 = 26 signed bits.
6. A tensor has values in [-6, 6] with one outlier at 60. What is the int8 scale, and what is the quantization step of the ordinary values?
Worked answer: The int8 scale is 60 / 127 = 0.47. The ordinary values (|x| <= 6) then use only codes -12 to 12, a step of 0.47 each, so their error is up to 0.24: about 4% of their range. Without the outlier the scale would be 6 / 127 = 0.047, ten times finer.
7. Why is saturation better than wrap-around for an activation, and when would wrap-around be acceptable?
Worked answer: Saturation limits the error to the clipped part of the value and keeps the sign; wrap-around turns a large positive into a large negative. Wrap-around is acceptable (and wanted) in modular arithmetic: counters, address arithmetic, hashes.
Appendix D
1. Compute [2, -1, 3] . [4, 0, -2]. Are the vectors closer to perpendicular or to the same direction?
Worked answer: 24 + (-1)0 + 3*(-2) = 8 + 0 - 6 = 2. The lengths are sqrt(14) = 3.74 and sqrt(20) = 4.47, so the cosine is 2 / 16.7 = 0.12: close to perpendicular.
2. Multiply [[1, 0], [2, 1]] by [[3, 1], [0, 2]]. Multiply them in the other order and compare.
Worked answer: [[1,0],[2,1]] x [[3,1],[0,2]] = [[3, 1], [6, 4]]. In the other order: [[3,1],[0,2]] x [[1,0],[2,1]] = [[5, 1], [4, 2]]. They differ: matrix products do not commute.
3. A product of a 6 x 8 matrix with an 8 x 5 matrix: what shape is the result, and how many multiply-adds?
Worked answer: 6 x 5; 6 * 8 * 5 = 240 multiply-adds.
4. Compute the arithmetic intensity (int8) of a 1 x 1024 vector times a 1024 x 1024 matrix.
Worked answer: Multiply-adds: 1 * 1024 * 1024 = 1,048,576. Bytes: 1,024 + 1,048,576 + 1,024 = 1,050,624. Intensity: about 1.0 operation per byte.
5. Why does softmax subtract the maximum before exponentiating? Does it change the result?
Worked answer: The exponential of a large score overflows. Subtracting the maximum from every score multiplies numerator and denominator by the same factor exp(-max), so the result is unchanged.
6. Softmax of [0, 0, 0, 0]: what is it, and what does it say about attention with all scores equal?
Worked answer: Softmax of four equal scores is [0.25, 0.25, 0.25, 0.25]: the output of attention is the plain average of the value rows: every cached token counts equally.
7. Why does the outer-product view suit a systolic array better than the dot-product view?
Worked answer: A systolic array receives one column of the left operand and one row of the right at each step and updates a running sum in every cell; the outer-product view is exactly that sequence. The dot-product view needs a whole row and a whole column present at once for one output.
Appendix E
1. Count the parameters of a model with 24 layers, d = 1024, f = 4096 (two-matrix FFN) and a vocabulary of 50,000, with a separate output matrix.
Worked answer: Per layer: 4 * 1024^2 = 4,194,304 attention weights plus 2 * 1024 * 4096 = 8,388,608 FFN weights = 12,582,912; times 24 layers = 301,989,888. Plus the embedding and output matrices: 2 * 50,000 * 1024 = 102,400,000. Total about 404 million parameters.
2. Why does the attention of token t only look at tokens up to t? What stops it looking ahead during decode?
Worked answer: Tokens are generated left to right: at decode time the cache holds only earlier tokens (and the current one), so there is nothing ahead to look at. During prefill and training a causal mask forbids it (Chapter 16 builds that mask from slices).
3. Compute the KV cache per token of a model with 40 layers, 8 KV heads of width 128, in int8. How many requests of 8,192 tokens fit in 24 GiB?
Worked answer: 2 * 40 * 8 * 128 = 81,920 bytes = 80 KiB per token. A request of 8,192 tokens holds 640 MiB. 24 GiB / 640 MiB = 38.4, so 38 requests (ignoring the weights, which also need room).
4. Why is decode memory-bound but prefill not? Express it as operations per weight byte.
Worked answer: Decode multiplies each weight by one activation, so about 1 operation per weight byte; prefill multiplies each weight by one activation per prompt token: about as many operations per weight byte as there are tokens in the prompt (512 in the example).
5. A residual connection adds the block's output to its input. What would happen to the signal after 100 layers without them?
Worked answer: Without the identity path each layer must reproduce the whole signal as well as add to it; the signal would be distorted by every layer and, in training, gradients would shrink to nothing along 100 layers. The residual lets each block learn a small correction.
6. Greedy against sampling: which gives the same output twice, and why does a test suite care?
Worked answer: Greedy decoding gives the same output every time, so a test can compare with a known answer. Sampling gives different outputs on different runs (unless the random generator is fixed), so a test could only check statistics.
Appendix F
1. Why does a row hit cost less than a row miss? What does the precharge do?
Worked answer: A row hit finds the row already in the row buffer and only needs the column access. A precharge closes the open row (writes it back to the cells and readies the bank), which must happen before another row can be activated; a miss pays precharge, activate and column access.
2. A DRAM channel delivers 25.6 GB/s at peak. How long does it take to stream the 7 GB of an int8 7B model once?
Worked answer: 7e9 bytes / 25.6e9 bytes per second = 0.27 s per pass, so about 3.7 tokens per second at best on one such channel.
3. Why does one request at a time give 3.8 GB/s from a memory whose peak is 25.6?
Worked answer: Each request has to wait the whole access latency (14 ns for a row hit plus the 2.5 ns burst) before the next one is issued: 64 bytes per 16.5 ns = 3.9 GB/s. With eight in flight the latencies overlap and the bus stays busy.
4. Why is a stride of 4 KiB bad for the toy model's banks? What would you change in the address mapping?
Worked answer: A stride of 4 KiB is exactly 64 lines, and the bank is the line number mod 8, so every access goes to the same bank and the banks cannot overlap. Address mappings hash several higher address bits into the bank number (for example, XOR them in) so that regular strides spread over the banks.
5. An accelerator has 1 TB/s of HBM and a 7B int8 model. What is the best decode speed at batch 1? At batch 8, if the weights are read once per step and the cache is neglected?
Worked answer: Batch 1: 1e12 / 7e9 = 143 tokens per second. Batch 8: the weights are read once per step, so each of the 8 requests still receives about 143 tokens per second and the chip delivers about 1,140 tokens per second in total (neglecting the cache, which is what Chapter 9 adds).
6. Which of the book's chip assumptions would change if the memory were real DRAM, and which would not?
Worked answer: Unchanged: the SRAM scratchpad's cycle counts, the arithmetic, the instruction-level counts, and the roofline's shape (streaming weights is the good case). Changed: the fixed 8-cycle DMA latency (a real DRAM has pattern-dependent latency and bandwidth), and anything that gathers small pieces.
Appendix G
1. Name the stages between Verilog and a netlist, and say what each does in one sentence.
Worked answer: Elaboration (read the language and build the module hierarchy), proc (turn procedural blocks into logic and flip-flops), optimization (remove redundant logic), technology mapping (choose cells from the library), and a final optimization pass (ABC).
2. Why can simulation never prove two circuits equivalent, and what does a miter do differently?
Worked answer: Simulation checks only the inputs it tries, at most a tiny fraction of 2^n. A miter feeds both designs the same inputs and a SAT solver searches for an input on which the outputs differ; if the search ends with none, there is none, for all inputs.
3. The counterexample for the broken voter is a = 0, b = 1, c = 1. Compute both outputs by hand.
Worked answer: Correct voter: majority of (0, 1, 1) is 1. Broken voter: (a & b) | (a & c) = (0 & 1) | (0 & 1) = 0. They differ, so this is a counterexample.
4. Why are the three 8-bit adders identical after synthesis but the 32-bit ones not?
Worked answer: With 8 bits the carry chain is short and the logic optimizer restructures all three descriptions to the same netlist (37 cells); the extra logic of a prefix tree only pays off, and is only visible, as the width grows (at 32 bits the delays are 3.65 against 2.30 ns).
5. What does logic synthesis not know that place-and-route does? Name two things that make real timing worse than the model's.
Worked answer: Place-and-route knows where the cells are and how long the wires are, how many gates each output drives, and how late the clock arrives at each flip-flop. Any two of: wire delay, fan-out loading, clock skew and uncertainty, on-chip variation, crosstalk.
6. Why is area in "NAND2 equivalents" a reasonable unit, and what is its weakness?
Worked answer: A NAND2 is a convenient unit that is independent of the library's real sizes, so areas of designs can be compared. Its weakness is that it hides wires, congestion and the fact that flip-flops and large cells do not scale like NAND gates; it is a relative, not a physical, measure.